The problem for RNN training with DataParallel

hello, today I train the nn.LSTM with multi-gpu by nn.DataParallel. I set the batch_size=12 in data.DataLoader, so the shape of input is (12, T, *), T represents the max frame in the 12 sentences(these 12 sentences has been padded into equal length), and * represents the dimension of the feature for each frame. the number of gpu is 3.
the model is as follows:
############################################################
train_rnn_pack_sort.py[115] 2018-55-16 09:55:20 INFO: Let’s use 3 GPUs!
train_rnn_pack_sort.py[126] 2018-55-16 09:55:20 INFO: DataParallel(
(module): LSTM(
(lstm): Sequential(
(0): LSTM(840, 256, batch_first=True, bidirectional=True)
(1): LSTM(512, 256, batch_first=True, bidirectional=True)
(2): LSTM(512, 256, batch_first=True, bidirectional=True)
(3): LSTM(512, 256, batch_first=True, bidirectional=True)
(conn): LSTM(512, 4800, batch_first=True, bidirectional=True)
)
)
)
###########################################################
the code for using the nn.DataParallel
########################################
if th.cuda.is_available():
if args.multi_gpu == 1:
if th.cuda.device_count() > 1:
logger.info(“Let’s use {} GPUs!”.format(th.cuda.device_count()))
nnet = nn.DataParallel(nnet, device_ids=[0,1,2]) # dim = 0 [30, xxx] → [10, …], [10, …], [10, …] on 3 GPUs
elif th.cuda.device_count() == 1:
logger.info(“!!!WARNINGS:Only 1 GPU detected and Let’s use the only one GPUs!!!”)
else:
logger.info(“!!!ERROR!!!”)
else:
logger.info(“!!!Training on single GPU!!!”)

else:
    logger.info("!!!WARNINGS:NO GPUs detected! AND The Net Will Be Trained On CPU!!!")
logger.info(nnet)

###########################
the propagation of the model is as follows:
###########################
class LSTM(nn.Module):
def init(self, input_size, hidden_layer, hidden_size, num_classes,
rnn_type=‘lstm’, dropout=0.0, bidirect=True, residual=False):
super(LSTM, self).init()
if bidirect:
layer = [nn.LSTM( input_size=input_size, hidden_size=hidden_size, batch_first=True, bidirectional=bidirect, dropout=dropout)]
for i in range(hidden_layer):
layer.append(nn.LSTM(hidden_size2, hidden_size, batch_first=True, dropout=0.0, bidirectional=bidirect))
self.lstm = nn.Sequential(layer)
self.lstm.add_module(“conn”,nn.LSTM(hidden_size
2, num_classes, batch_first=True, dropout=0.0, bidirectional=bidirect))
def forward(self, x, input_len):
max_length = x.shape[1]
x = rnn_pack.pack_padded_sequence(x, input_len, batch_first=True)
x = self.lstm(x)
out , _ = rnn_pack.pad_packed_sequence(x, total_length=max_length, batch_first=True)
return out
##########################
def train_one_epoch(nnet, criterion, optimizer, train_loader, num_parallel, is_rnn=False):
nnet.train()
pos_frames = 0.0
train_frames = 0.0
for index, (key, feats, labels, len_list) in enumerate(train_loader):
print “=============”
print key
print feats.shape ##(12,T,
)
print labels.shape ##(12,T)
#print type(len_list)
#print len_list.shape
print “=============”
labels = labels.view(labels.shape[0], labels.shape[1])
input_len = np.array(len_list)
input_sort_id = np.argsort(-input_len)
input_len = input_len[input_sort_id]
feat_mat = feats[th.LongTensor(input_sort_id)]
feat_mat = Variable(feat_mat.cuda())
input_unsort_id = th.LongTensor(np.argsort(input_sort_id))
optimizer.zero_grad()
if is_rnn:
label_mat = labels.view(labels.size(0) * labels.size(1))
targets = Variable(label_mat.cuda())
out = nnet(feat_mat, input_len)
out = out[input_unsort_id]
out_num = out.shape[2]
max_frame = int(max(len_list))
.
.
.
but the error occurs:
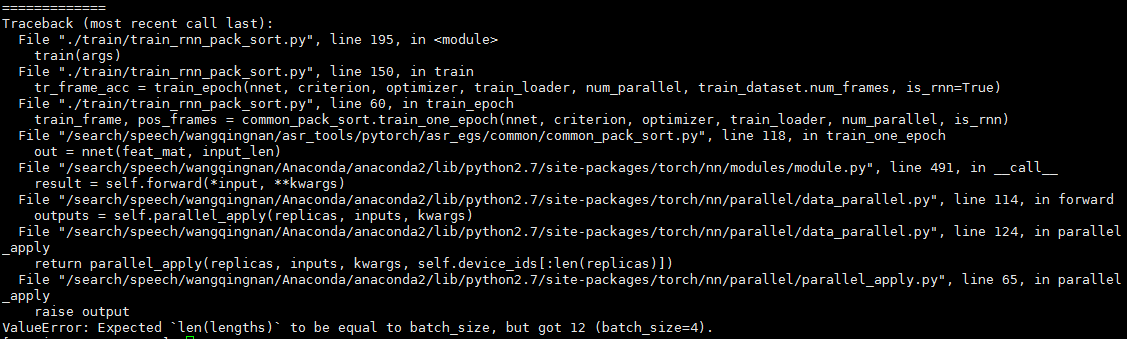

Any help would be appreciated…

In DataParallel, you need to set your batch size in forward method. Also, please format your code when pasting since it is not readable now.

Thanks for your application,but I wonder how to set batch size in forward method ?

It should be straightforward by taking the length of the input. If not, you may need to format your code first to make sure people could read that.

I 'm very sorry…here are the formated code.

class LSTM(nn.Module):
def init(self, input_size, hidden_layer, hidden_size, num_classes,
rnn_type=‘lstm’, dropout=0.0, bidirect=True, residual=False):
super(LSTM, self).init()
if bidirect:
layer = [nn.LSTM( input_size=input_size, hidden_size=hidden_size, batch_first=True, bidirectional=bidirect, dropout=dropout)]
for i in range(hidden_layer):
layer.append(nn.LSTM(hidden_size2, hidden_size, batch_first=True, dropout=0.0, bidirectional=bidirect))
self.lstm = nn.Sequential(layer)
self.lstm.add_module(“conn”,nn.LSTM(hidden_size2, num_classes, batch_first=True, dropout=0.0, bidirectional=bidirect))
def forward(self, x, input_len):
max_length = x.shape[1]
x = rnn_pack.pack_padded_sequence(x, input_len, batch_first=True)
x = self.lstm(x)
out , _ = rnn_pack.pad_packed_sequence(x, total_length=max_length, batch_first=True)
return out
def train_one_epoch(nnet, criterion, optimizer, train_loader, num_parallel, is_rnn=False):
nnet.train()
pos_frames = 0.0
train_frames = 0.0
for index, (key, feats, labels, len_list) in enumerate(train_loader):
print “=============”
print key
print feats.shape ##(12,T,)
print labels.shape ##(12,T)
#print type(len_list)
#print len_list.shape
print “=============”
labels = labels.view(labels.shape[0], labels.shape[1])
input_len = np.array(len_list)
input_sort_id = np.argsort(-input_len)
input_len = input_len[input_sort_id]
feat_mat = feats[th.LongTensor(input_sort_id)]
feat_mat = Variable(feat_mat.cuda())
input_unsort_id = th.LongTensor(np.argsort(input_sort_id))
optimizer.zero_grad()
if is_rnn:
label_mat = labels.view(labels.size(0) * labels.size(1))
targets = Variable(label_mat.cuda())
out = nnet(feat_mat, input_len)
out = out[input_unsort_id]
out_num = out.shape[2]
max_frame = int(max(len_list))
.
.
.
if th.cuda.is_available():
if args.multi_gpu == 1:
if th.cuda.device_count() > 1:
logger.info(“Let’s use {} GPUs!”.format(th.cuda.device_count()))
nnet = nn.DataParallel(nnet, device_ids=[0,1,2]) # dim = 0 [30, xxx] -> [10, …], [10, …], [10, …] on 3 GPUs
elif th.cuda.device_count() == 1:
logger.info("!!!WARNINGS:Only 1 GPU detected and Let’s use the only one GPUs!!!")
else:
logger.info("!!!ERROR!!!")
else:
logger.info("!!!Training on single GPU!!!")
else:
    logger.info("!!!WARNINGS:NO GPUs detected! AND The Net Will Be Trained On CPU!!!")
logger.info(nnet)

It seems you are doing the sort/unsort stuff for sequence packing out of the forward method, which you should do inside based on your input (param #1 for forward method). What happened here is, each of your GPU got 4 sequences, with a sorted length of 12 sequences.

do you mean that i should sort the sequence in the forward method rather than in the train_one_epoch method?

yes you should try that

ok,thank you very much,I‘ll try it。

here is the revised code. x is the input tensor (12, T, *), len_list is a tuple with 12 elements which represent the length of sequence(the number of frames).

    def forward (self, x, len_list):
        input_len = np.array(len_list)
        input_sort_id = np.argsort(-input_len)
        input_len = input_len[input_sort_id]
        x = x[th.LongTensor(input_sort_id)]
        max_length = x.shape[1]
        x = rnn_pack.pack_padded_sequence(x, input_len, batch_first=True)
        x = self.lstm(x)
        out , _ = rnn_pack.pad_packed_sequence(x, total_length=max_length, batch_first=True)
        return out

after i run this script again,the error occurs as follows:

Traceback (most recent call last):
  File "./train/train_rnn_pack_sort.py", line 195, in <module>
    train(args)
  File "./train/train_rnn_pack_sort.py", line 150, in train
    tr_frame_acc = train_epoch(nnet, criterion, optimizer, train_loader, num_parallel, train_dataset.num_frames, is_rnn=True)
  File "./train/train_rnn_pack_sort.py", line 60, in train_epoch
    train_frame, pos_frames = common_pack_sort.train_one_epoch(nnet, criterion, optimizer, train_loader, num_parallel, is_rnn)
  File "/search/speech/wangqingnan/asr_tools/pytorch/asr_egs/common/common_pack_sort.py", line 103, in train_one_epoch
    out = nnet(feats, len_list)
  File "/search/speech/wangqingnan/Anaconda/anaconda2/lib/python2.7/site-packages/torch/nn/modules/module.py", line 491, in __call__
    result = self.forward(*input, **kwargs)
  File "/search/speech/wangqingnan/Anaconda/anaconda2/lib/python2.7/site-packages/torch/nn/parallel/data_parallel.py", line 114, in forward
    outputs = self.parallel_apply(replicas, inputs, kwargs)
  File "/search/speech/wangqingnan/Anaconda/anaconda2/lib/python2.7/site-packages/torch/nn/parallel/data_parallel.py", line 124, in parallel_apply
    return parallel_apply(replicas, inputs, kwargs, self.device_ids[:len(replicas)])
  File "/search/speech/wangqingnan/Anaconda/anaconda2/lib/python2.7/site-packages/torch/nn/parallel/parallel_apply.py", line 65, in parallel_apply
    raise output
AttributeError: 'tuple' object has no attribute 'size'

any help would be appreciated